Knowledge base
Each tenant can have a set of markdown documents the bot searches when a visitor asks a factual question - hours, policies, FAQs, product details. Retrieval is grounded: when nothing relevant is found, the bot says it doesn't know instead of guessing.
Adding documents
Tenant → Knowledge base. Paste markdown with a title, save - the document is chunked, embedded and searchable immediately. Saving under an existing title replaces that document.
Two rules make retrieval precise:
- Structure with headings. Chunking is heading-aware: each
##section becomes a retrieval unit with its breadcrumb attached. One fact per section beats one wall of text. - Only counter-safe facts. Everything here can reach a visitor. Nothing internal, no wholesale prices, nothing you would not say out loud at the counter.
Import from a PDF
Facts often already live in a PDF - a handbook, a flyer, a policy sheet. Tenant → Knowledge base → Import from a PDF walks it in, and the design principle is that the free work happens first:
- Analyze (free, no model). The text is read out of the file, and mechanical junk - repeated headers and footers, page numbers, table-of-contents dot lines - is stripped deterministically. You get a plain-words cost estimate for the optional AI step before deciding anything, plus targeted warnings: a scanned PDF (photos of pages, nothing to read), table-heavy content (prices belong in live tools, not the KB), or a file big enough to be worth splitting.
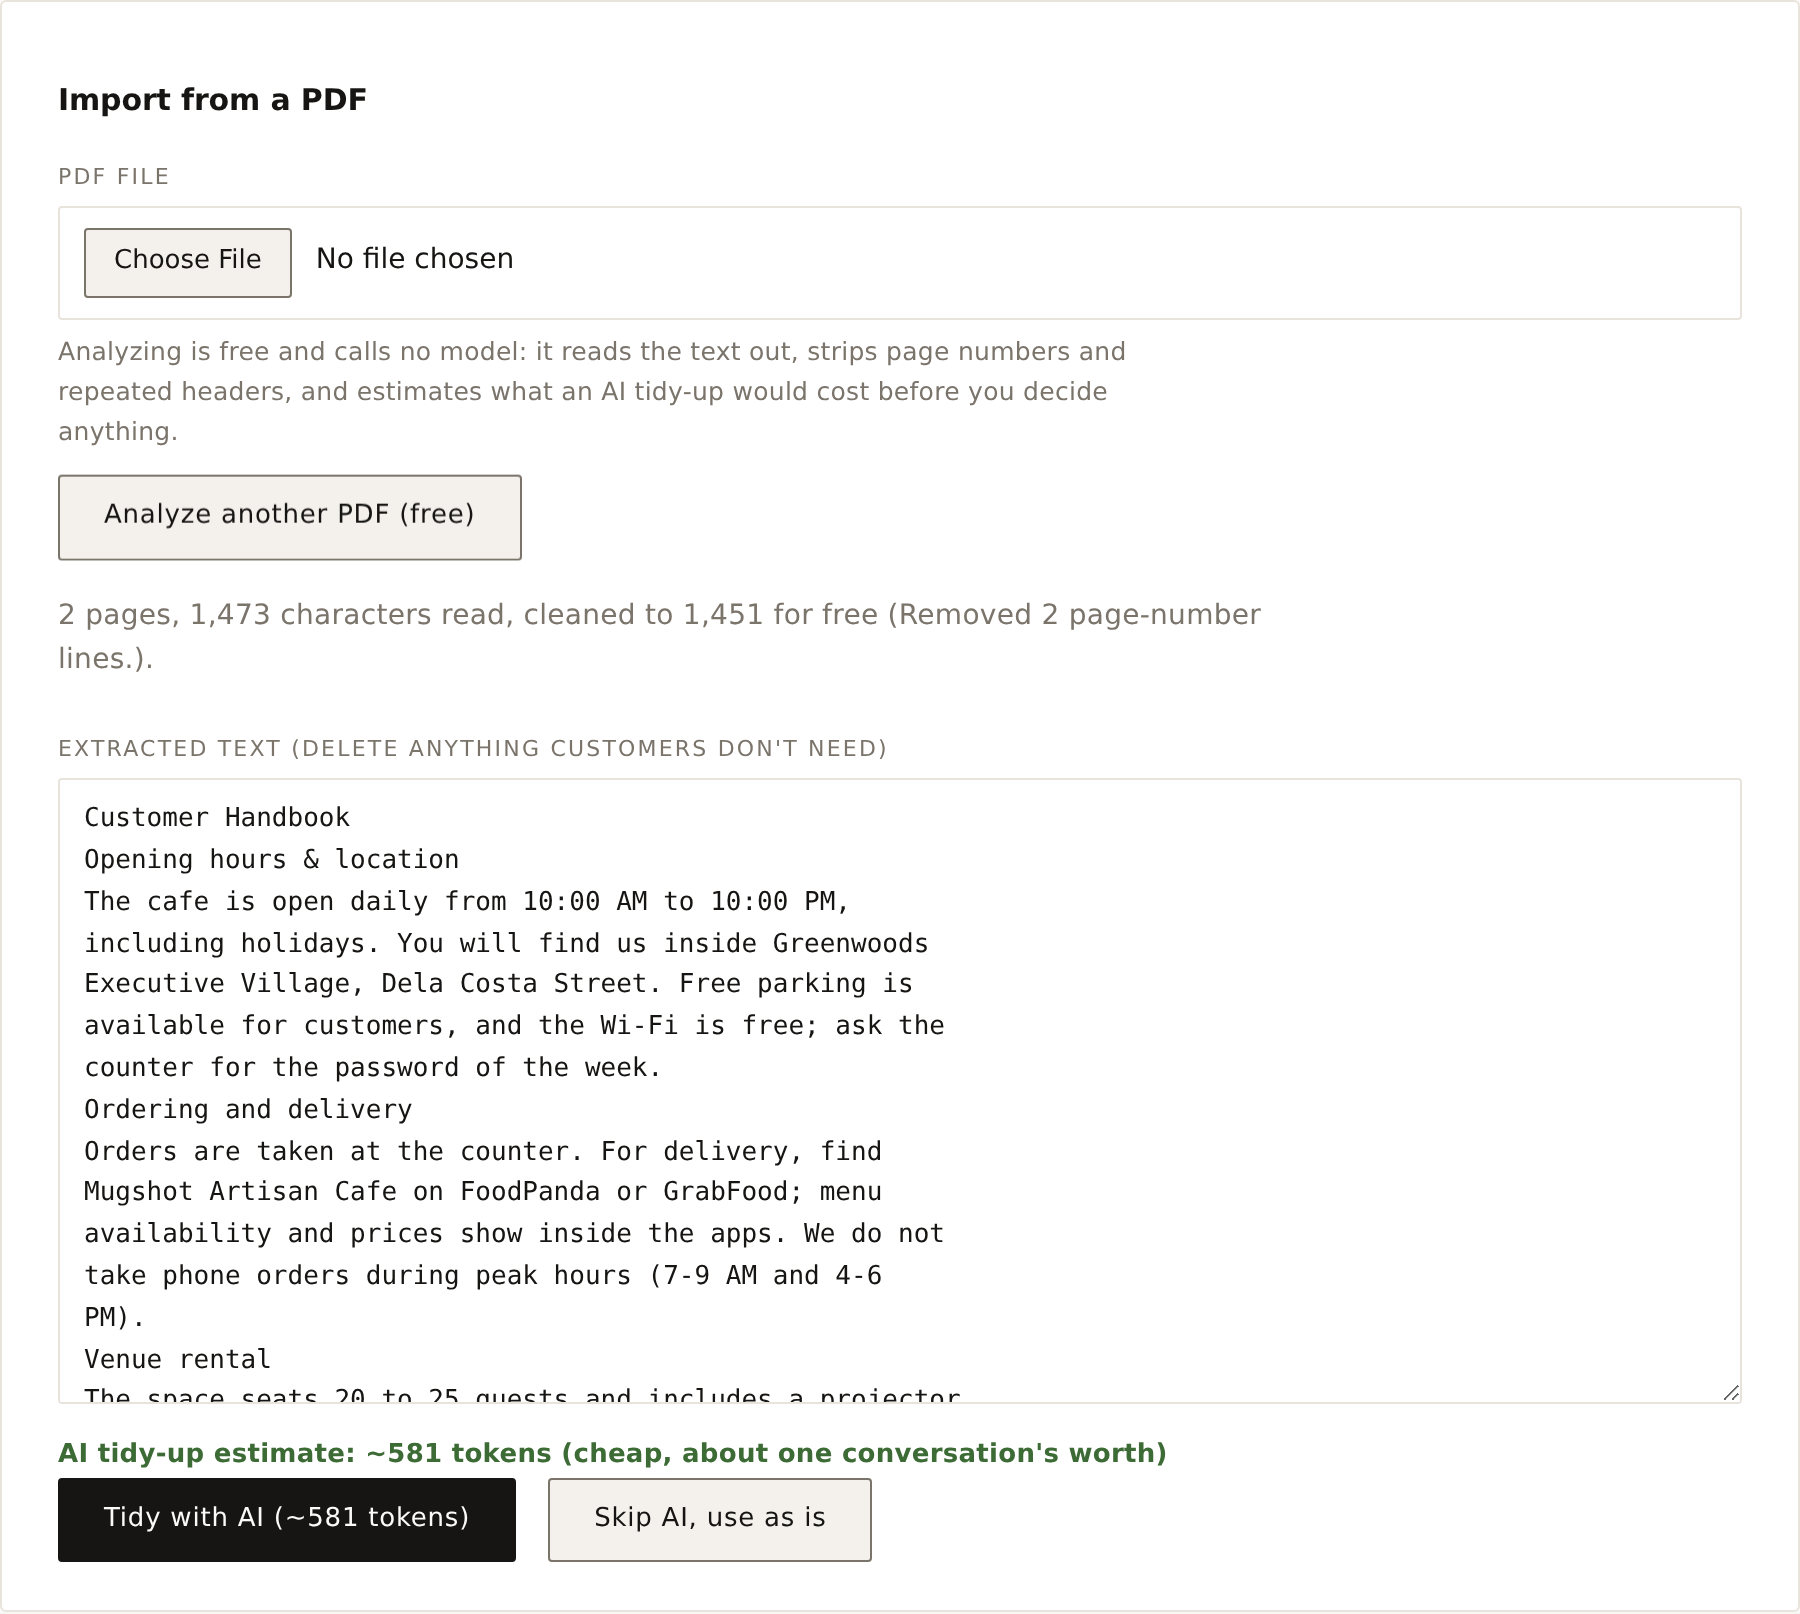
Trim. The text box is the selection tool: delete anything customers never ask about, and the estimate updates as you cut.
Tidy with AI - or skip it. The one paid step carries its price on the button, and reports the tokens actually used afterwards. The model reorganizes the text into short
##sections (the shape retrieval likes) but invents nothing; read the result before saving, because you know the facts.
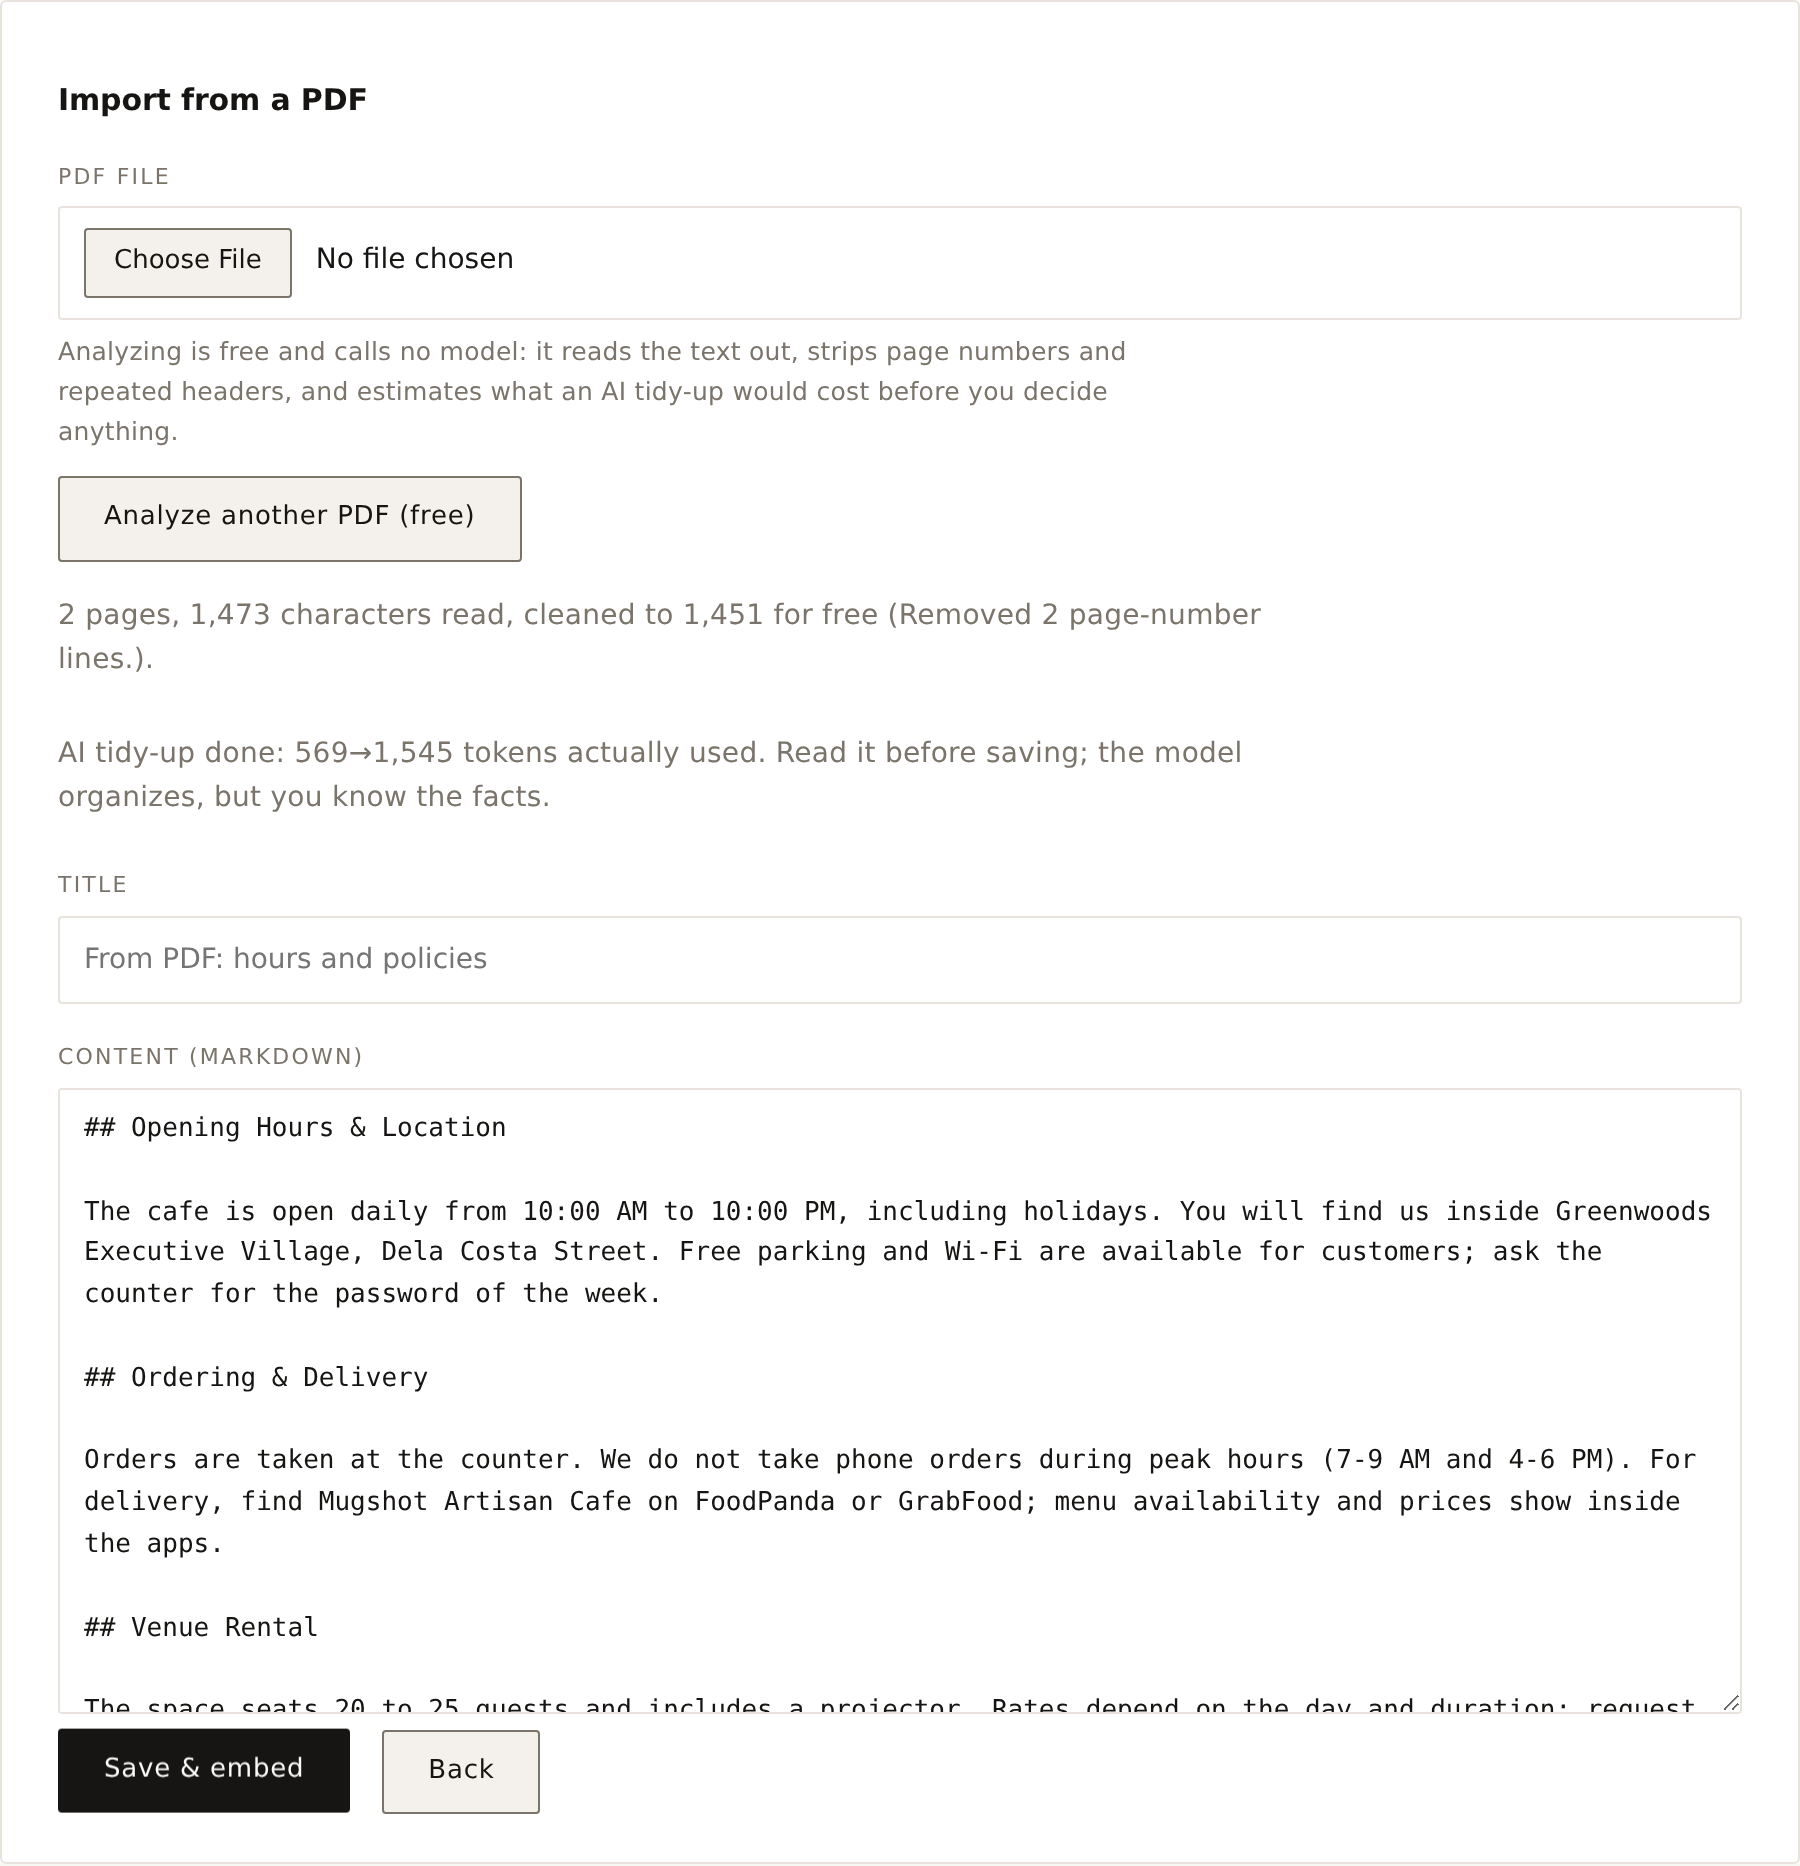
- Save & embed - from here it is a normal document like any other.
A green estimate means "about one conversation's worth" - just go ahead. The gauge exists to catch the accidental 300-page upload, not to make small imports feel expensive.
Owner-friendly, screen-by-screen version: Turn a PDF into knowledge.
Wiring it to the bot
Enable the search_kb tool pack on the tenant page. Without it, the documents exist but the bot never reads them.
Checking quality
The table shows a chunk count per document - one giant chunk or fifty tiny ones is a sign the headings need work. Developers with a repo clone can go further:
docker compose exec app npm run kb:ingest -- <tenant-slug>     # bulk-ingest kb/<slug>/*.md
docker compose exec app npm run kb:eval -- <tenant-slug>       # recall@k: does the right doc come back?
docker compose exec app npm run eval:answers -- <tenant-slug>  # judge-graded: is the final ANSWER right?
The recall eval measures retrieval; the answers eval sends real chat turns and has a second model grade each reply for faithfulness (nothing invented) and completeness (the required facts arrive) - numbers, not feelings.
Backup and bulk editing (CSV)
Export CSV on the Knowledge base page downloads every document as a two-column spreadsheet (title, content). Edit it in Excel or Google Sheets - fix facts, add rows - then Import from CSV brings it back: rows match by title, changed documents are re-embedded, unchanged ones are skipped. Export before big edits and you always have a restore point.
Instant repeat answers
Common opening questions ("what time do you open?") are served from a semantic cache: an answer already given for a near-identical first message returns instantly, at zero model cost. The cache clears itself whenever you save or delete knowledge or tenant settings, so editing a fact never leaves a stale cached answer behind.